Industry–Academia–Research–Application

Xiangjiang Laboratory · Digital Intelligence Technology Application and Innovation Research Institute

Energy-efficient heterogeneous computing + Domestic Chinese on-device AI hardware + Specialized model accelerators

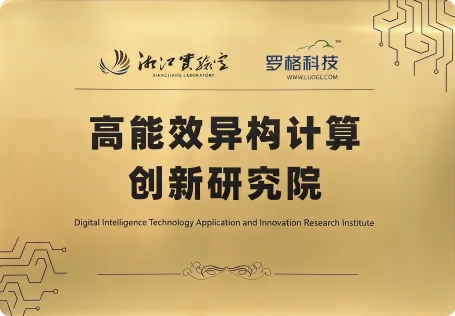
Plaque of the Digital Intelligence Technology Application and Innovation Research Institute

Xiangjiang Laboratory Digital Intelligence Technology Application and Innovation Research Institute

The Xiangjiang Laboratory Digital Intelligence Technology Application and Innovation Research Institute focuses on China's domestic computing ecosystem and on-device AI hardware architecture. Addressing national computing industry priorities, it works on energy efficiency and domestic technology adoption for edge AI, providing a strong compute foundation for the AI Plus initiative.

Guided by hardware–software co-design, device–cloud integration, and maximum energy efficiency, the institute works with chip vendors and manufacturers on key hardware technologies. Research includes dedicated on-device AI hardware and adaptation to China's domestic IT ecosystem, moving AI compute from cloud to edge for secure, smooth large-model operation on local devices.

Founded in July 2022, Xiangjiang Laboratory is Hunan's first provincial laboratory led by the provincial government. Headquartered in Beidou Industrial Park, Changsha High-Tech Zone, Hunan Xiangjiang New Area, it is a major innovation platform for advanced computing and AI. Established by the Hunan Department of Science and Technology and led by Hunan University of Technology and Business, it follows a “headquarters + branches + innovation centers” 1346 framework, focusing on four areas including data intelligence and high-performance computing, and six application fields including smart manufacturing and healthcare.
Research positioning

On-device heterogeneous computing for Chinese chips

On-device heterogeneous computing for Chinese chips

Full-stack hardware–software co-design ecosystem

Full-stack hardware–software co-design ecosystem

From technology validation to products and standards

From technology validation to products and standards

Collaborative joint R&D

Collaborative joint R&D

Research areas

Domestic on-device computing and prototypes

Domestic on-device computing and prototypes

Performance and energy benchmarks: test compute, inference speed, power, and latency across Chinese chips, producing systematic evaluation reports to guide selection and combinations.

Device prototyping and integration: design heterogeneous on-device prototypes with Chinese chips, integrate hardware and software, validate scheduling, and test stability and performance under real workloads.

Device standards: draft standards for domestic on-device AI hardware covering performance benchmarks, interface protocols, and security, including power and thermal testing methods.

Low-power inference resource management: explore resource allocation and inference scheduling on low-power hardware to better balance power and performance.

Domestic AI frameworks and inference engines

Domestic AI frameworks and inference engines

Framework research and evaluation: systematically assess CANN, MUSA, and other frameworks across Chinese chips for features, performance, and adaptation costs, with research and comparison reports.

Inference scheduling and operator optimization: design scheduling systems and optimize operators on existing frameworks to improve device and edge inference efficiency.

SDKs and development tools: provide SDKs, sample code, and API documentation for optimized frameworks, giving third-party developers ready-to-use environments and toolchains.

Framework adaptation and migration standards: define operator interfaces, scheduling standards, and compiler adaptation processes for domestic AI inference frameworks, lowering cross-platform model migration barriers.

Small on-device model architectures and efficient inference

Small on-device model architectures and efficient inference

Model architecture research: track Mamba, graph neural networks (GNNs), and heterogeneous Transformers, assessing their applicability and performance on devices.

On-device inference framework design: use these architectural characteristics to design device-friendly inference frameworks, optimizing operators and scheduling for Chinese chip platforms.

Efficient small-parameter models: explore architectures that preserve accuracy while reducing memory use and compute costs.

Quantization, distillation, and compression: combine these techniques to build lightweight on-device models and establish evaluation methods and standards.

Fine-tuning industry and domain-specific on-device small models

Fine-tuning industry and domain-specific on-device small models

Domain-specific fine-tuning: design and validate small-model tuning approaches for industry tasks, improving accuracy and response speed in specialized scenarios.

Industry datasets: build high-quality datasets for different industries to support small-model training and fine-tuning.

Evaluation standards and interfaces: define consistent small-model assessment and interface standards for tax, accounting, healthcare, law, and other industries.

Scenario-adaptive inference scheduling: study dynamic task scheduling based on inference pipelines and device status for stable performance across workloads and hardware conditions.

Research outcomes

Research reports & Technical white papers

Research reports & Technical white papers

Prototype devices & Toolchains

Prototype devices & Toolchains

Lightweight & Industry-specific small models

Lightweight & Industry-specific small models

Standards & Patents

Standards & Patents

News Center